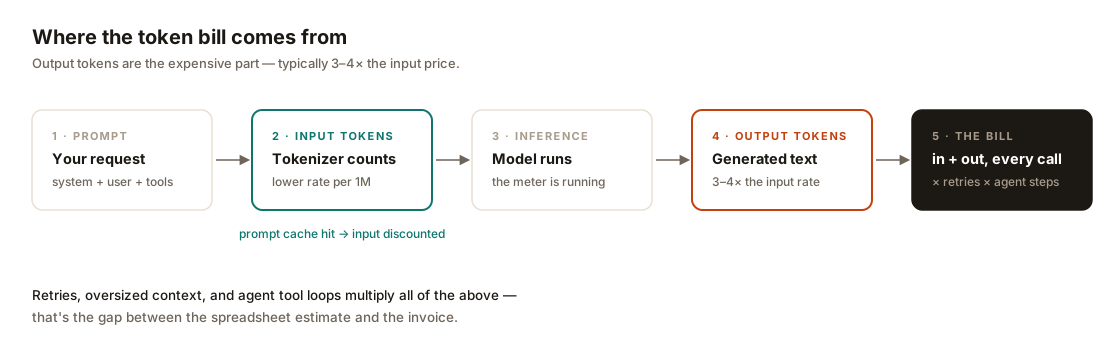
Every LLM app has two bills: the one you estimated in a spreadsheet, and the one that shows up. The gap between them is almost never the model price — it’s the calls you didn’t count: retries, oversized context, debug loops, and the “just one more tool call” agent steps.
You can’t optimize what you don’t measure. Here’s the setup I use before touching any cost lever.
Count every call
Wrap your client once. Log the model, input tokens, output tokens, latency, and what the call was for. The “for” matters more than you’d think — it’s how you find the expensive feature nobody uses.
import time, json

ledger = []

def traced_call(client, *, purpose, model, **kwargs):
    start = time.time()
    resp = client.chat.completions.create(model=model, **kwargs)
    usage = resp.usage
    ledger.append({
        "purpose": purpose,
        "model": model,
        "in_tokens": usage.prompt_tokens,
        "out_tokens": usage.completion_tokens,
        "seconds": round(time.time() - start, 2),
    })
    return resp

def report(prices):
    """prices: {model: (input_per_1k, output_per_1k)}"""
    total = 0.0
    by_purpose = {}
    for row in ledger:
        pin, pout = prices[row["model"]]
        cost = row["in_tokens"] / 1000 * pin + row["out_tokens"] / 1000 * pout
        total += cost
        by_purpose[row["purpose"]] = by_purpose.get(row["purpose"], 0) + cost
    print(f"total: ${total:.2f} across {len(ledger)} calls")
    for purpose, cost in sorted(by_purpose.items(), key=lambda kv: -kv[1]):
        print(f"  ${cost:7.2f}  {purpose}")
Run this for a week against production traffic (or a replayed sample). The output is always surprising: usually one purpose — summarization, a chatty agent loop, an embedding backfill — eats 60–80% of the bill.
The three levers, in order
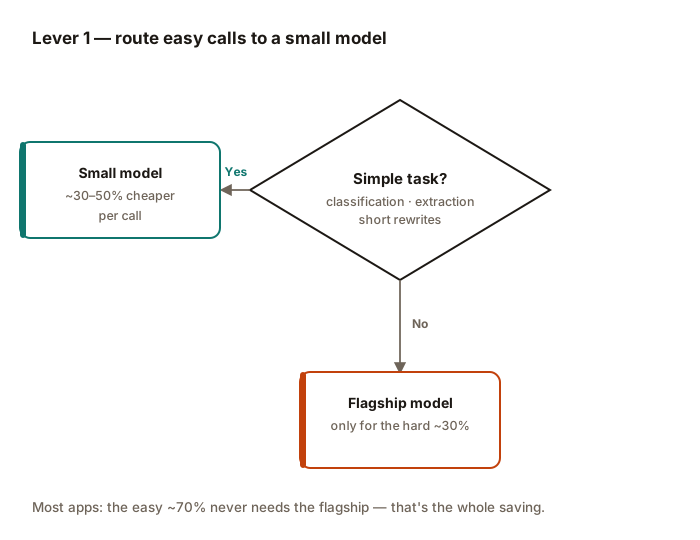
1. Route easy calls to a smaller model. Most apps send everything to the flagship model. Add a cheap classifier call (or even a heuristic) that sends simple tasks — classification, extraction, short rewrites — to a small model. This alone often cuts 30–50%.
2. Cache what’s repeatable. System prompts, few-shot examples, and reference documents get re-sent on every call. If your provider supports prompt caching, turn it on; if not, shorten what’s static. Measure input tokens before and after — that’s your caching win, in dollars.
3. Shrink the context, not the answer. Long context is the silent killer: you pay input price on every token, every call. Retrieve less, summarize history aggressively, and cap tool-call loops with a hard budget:
MAX_STEPS = 8  # an agent that needs more is stuck, not thinking

for step in range(MAX_STEPS):
    action = agent.next_step()
    if action.done:
        break
    action.execute()
else:
    raise BudgetExceeded("agent hit the step budget")
Measure quality, not vibes
Cost cuts are easy to justify and easy to regret. Before swapping models, build a tiny eval set — 30 to 50 representative inputs with expected outputs — and score both models on it. It doesn’t need to be fancy:
def score(model, cases):
    wins = 0
    for case in cases:
        out = traced_call(client, purpose="eval", model=model,
                          messages=[{"role": "user", "content": case["input"]}])
        if case["check"](out.choices[0].message.content):
            wins += 1
    return wins / len(cases)

print("flagship:", score("flagship-model", cases))
print("small:   ", score("small-model", cases))
If the small model scores within a couple of points on your cases, route to it. If it doesn’t, you now know exactly what the flagship premium buys you — and you can say so in a planning meeting with numbers instead of adjectives.
The rule of thumb
After doing this a few times, the pattern is consistent: measure for a week, route the easy 70% to a small model, cache the static 20%, and cap the loops. Most apps land 40–60% cheaper with no measurable quality drop — because the original setup was never measured in the first place.
The token bill isn’t a pricing problem. It’s an observability problem. Fix the observability and the pricing mostly fixes itself.